Learning from feedback
This is why AI assistants today understand what you mean far better than a few years ago, and not simply because they are bigger.
This is why AI assistants today seem to "get it" far better than a few years ago, and not simply because they are bigger.
What reinforcement learning from human feedback is
Picture a very bright new employee who does not yet know the company's culture. You do not write them an enormous rulebook. Instead, each time they produce something, you say clearly "this way works better", "that one is not quite right". Over many rounds of feedback, they come to understand what a good result means by your standard.
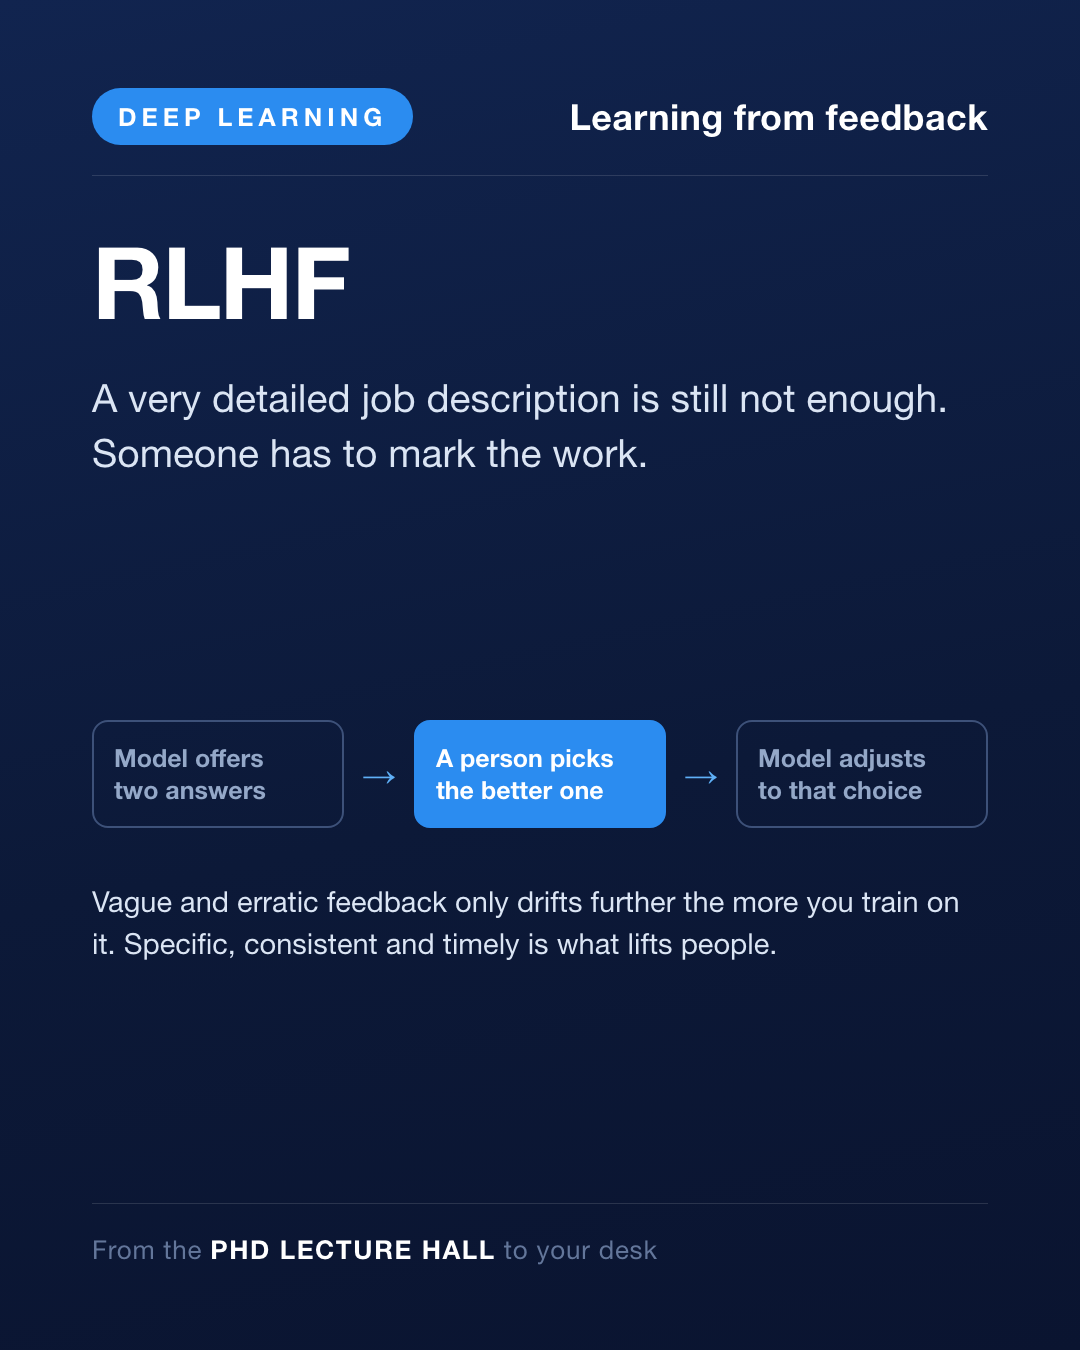
Reinforcement learning from human feedback, shortened to RLHF, does exactly that. The model produces several answers, people mark which is better, and the model is trained to lean towards the kind of answer that is preferred. In the InstructGPT research by Ouyang and colleagues in 2022, a model of only 1.3 billion parameters, after being trained with human feedback, was preferred by users over the original 175 billion parameter GPT-3, roughly a hundred times larger.
How this applies to running a business
I find this lesson very close to how a team matures. Capability comes not only from hiring excellent people or writing a great many rules, but from the quality and frequency of feedback. Feedback that is specific, timely, and says plainly what worked and what did not, shapes behaviour more powerfully than any process document left in a drawer.
And as in training a model, feedback is only useful when the criterion for good is clear enough. If the manager is themselves vague about the standard, the team will learn towards a blurred target.
How specific is the feedback your team receives, and is the standard for a good result clear enough to everyone?